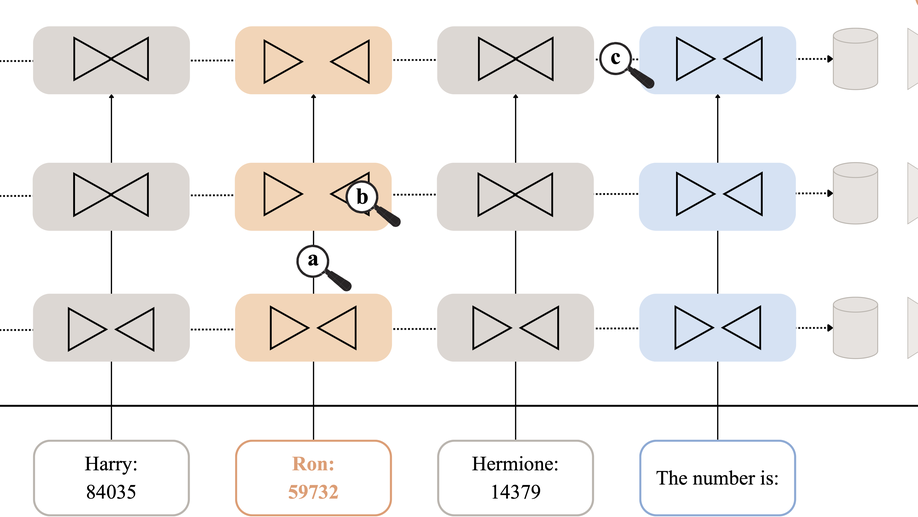
Mamba models underperform Transformers on in-context retrieval. This gap is usually attributed to Mamba's fixed-size recurrent state, which loses information as the context grows. We challenge this assumption by focusing on query-first retrieval, a setup in which the query precedes the context and state capacity should not be the binding constraint. We show that even in this setting Mamba lags substantially behind Transformers, despite its selection mechanism, which was designed to distinguish relevant content from distractors. We then demonstrate that the Mamba selection gates have sufficient control over the state updates to influence the model output: intervening on specific gates alone can swing accuracy between extremes. However, as gates are input-dependent, they require the incoming token's representation to encode its relevance to the query. We therefore probe token representations across layers, and find that the relevance signal emerges only gradually with model depth, and that the gates begin to reflect it only several layers deeper. Crucially, we find that gates in retrieval-critical layers are not yet aligned with relevance. The selection mechanism is thus expressive enough to solve the task, but it commonly operates on a relevance signal that has not yet arrived. Mamba's retrieval bottleneck therefore extends beyond state capacity: even when capacity is sufficient, the delayed emergence of relevance information across depth often prevents successful retrieval.
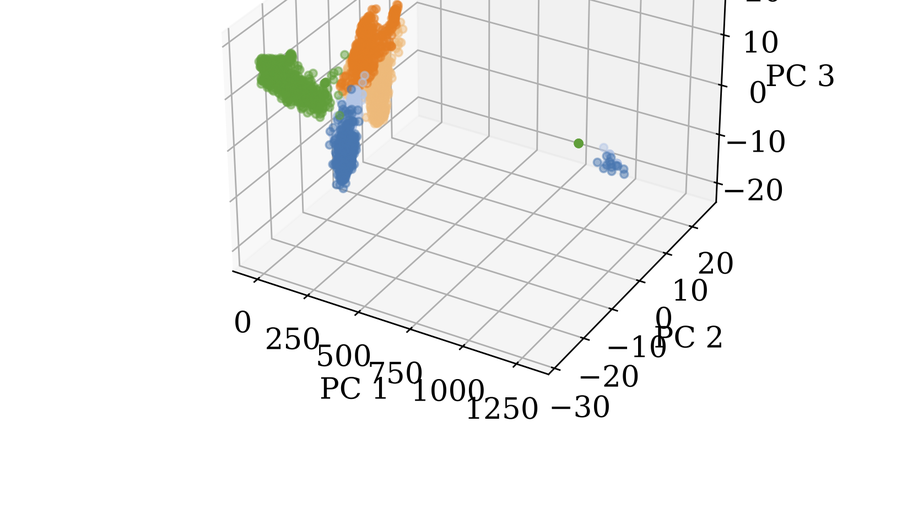
Recent state-space models (SSMs) such as Mamba achieve language modeling performance comparable to transformers despite relying on fundamentally different architectures. This raises an important question: how do these structural differences influence the geometry and functional nature of their internal representations? We study this question through a multi-scale analysis of representations in transformers, SSMs, and hybrid architecture. First, we find that SSMs distribute their representational information evenly across all dimensions, whereas transformer representations are heavily dominated by a single principal direction. By evaluating hybrid architectures, we observe that the representation space becomes increasingly skewed toward a single dominant direction after each attention layer. Next, we explore how the different geometric spread of representations impacts representational capacity through compressibility. Surprisingly, we find that despite their contrasting geometric structures, both architectures exhibit tightly matched effective capacities. We further investigate whether this skewed geometry affects how concepts are encoded. Using rank-constrained probes, we demonstrate that both architectures encode concepts in subspaces of surprisingly similar dimensionality. Furthermore, we demonstrate that the transformers' dominant principal direction does not inherently encode more conceptual information. Finally, we zoom in and examine the alignment between manifolds, either by analyzing representations of specific topics or by looking at the nearest neighborhoods of tokens, and find that they are highly aligned. Ultimately, our analysis suggests that while transformers and SSMs induce different usage of latent space, they display a striking functional convergence at the level of local semantic manifolds.
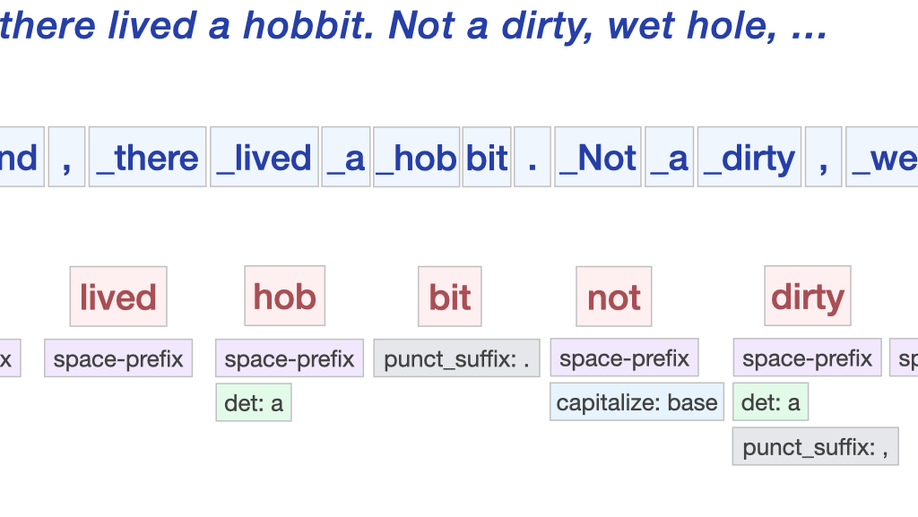
Language models process and generate text sequentially in token units, and the tokenizer determines how much text each inference step covers. Under standard tokenization, a short English phrase such as "On the table." is usually produced as four separate predictions for the preposition (On), article (the), noun (table), and punctuation (.), where each consumes a sequence position and adds inference cost. We introduce CoBPE, a compositional tokenization approach that represents such phrases as a lexical base token (table) attached with a small set of reusable surface modifiers, composed in embedding space at input and predicted jointly at output. In controlled pretraining from scratch at 780M and 1.3B scales, CoBPE shortens sequences by 30% and improves average downstream performance by 1.2 points relative to standard BPE under matched training compute. Our results suggest that part of what is now expressed through token sequences can instead be modeled through structured representations, opening a broad design space for more token-efficient and capable language models.
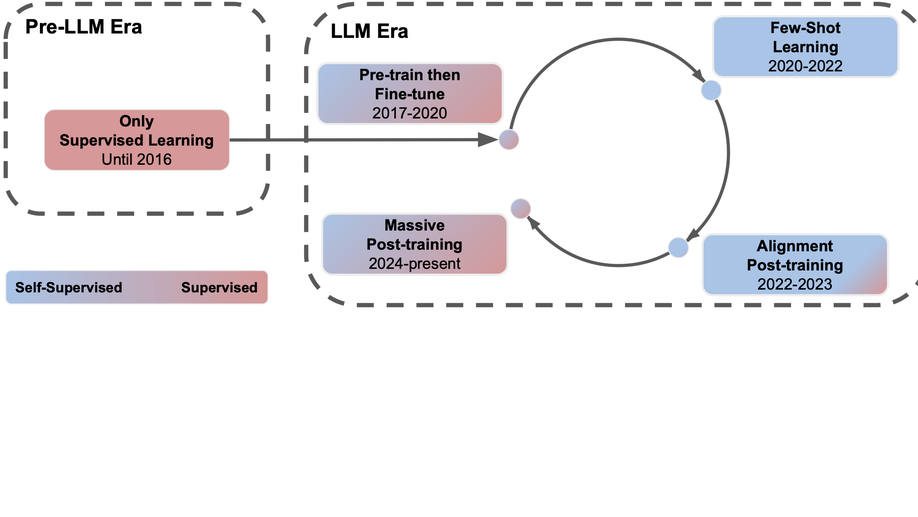
The prevailing paradigm for training LLMs has evolved to rely on a massive post-training phase consisting of SFT and RL. In this position paper, we argue that this methodology effectively marks a reversion to the ‘‘pre-train then fine-tune’’ approach of the BERT era, explicitly tailoring models to the desired behaviors and specific benchmarks on which they are evaluated. We begin with a historical overview of LLMs, describing the different phases of the LLM evolution. We argue that the current landscape is remarkably similar to the early days of LLMs, where task performance heavily relied on fitting the models to in-distribution datasets. To empirically demonstrate this, we compare pre-trained models to randomly initialized ones, by fine-tuning both variants on modern reasoning datasets and evaluating them on competitive math and code benchmarks. We show that models post-trained from scratch yield highly non-trivial performance. Our findings suggest that current post-training methodologies function primarily as a distribution-fitting mechanism. We finish by positing that developing generally capable models and systems requires moving beyond extensive post-training for predefined behaviors, shifting instead toward training procedures where models ‘‘learn how to learn’’.
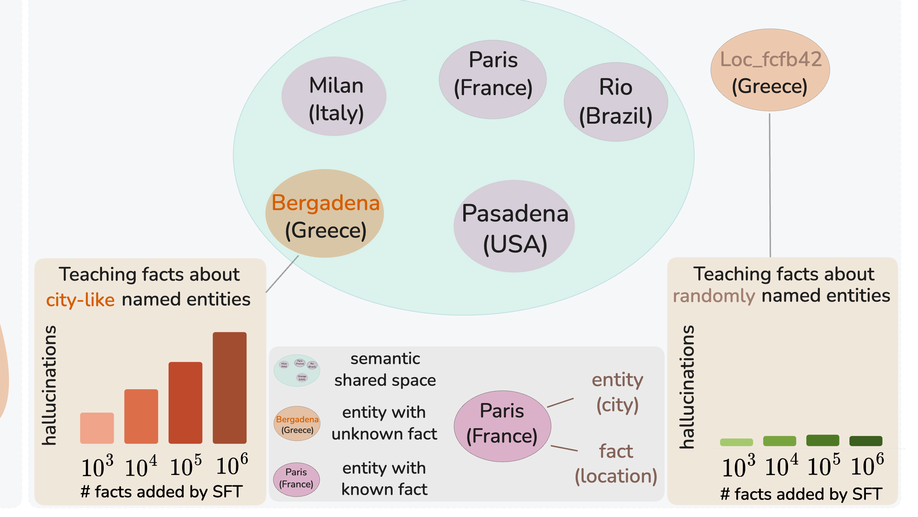
Large language models are prone to hallucinating factually incorrect statements. A key source of these errors is exposure to new factual information through supervised fine-tuning (SFT), which can increase hallucinations w.r.t. knowledge acquired during pre-training. In this work, we explore whether SFT-induced hallucinations can be mitigated using established tools from the continual learning literature, since they arise as a by-product of knowledge degradation during training. We propose a self-distillation-based SFT method that facilitates effective factual learning while minimizing hallucinations w.r.t. pre-existing knowledge by regularizing output-distribution drift. We also show that, in settings where new knowledge acquisition is unnecessary, suppressing factual plasticity by freezing parameter groups, can preserve task performance while reducing hallucinations. Lastly, we investigate the mechanism behind SFT-induced hallucinations through three hypotheses: capacity limitations, behavior cloning, and localized interference. Our experiments show that a main driver is interference among overlapping semantic representations, and that self-distillation succeeds by mitigating this interference.